High level architecture#

Fig. 1 High level architecture#
The platform is organized in three tiers: a storage layer, a cache layer, and a web layer.
Storage layer (Kvrocks)#
Kvrocks is the primary persistent storage for all vulnerability data. It runs on TCP (default port 10002) and uses RocksDB as its storage engine, providing a Redis-compatible protocol with significantly lower memory requirements.
Key storage patterns:
Vulnerabilities are stored by lowercase ID:
cve-2024-1234→ JSON blobMetadata:
cve-2024-1234:meta→ hash mapping meta types to UUIDsCross-references:
cve-2024-1234:link→ set of related vulnerability IDsSource indexes:
index:<source_name>→ sorted set of vulnerability IDsLast update tracking:
last_updateshash with per-source timestampsPrepared statistics, per source (written by
index_vulnerabilitiesandeuvd --stats-scan, read by/api/stats/*; a missing key means the figure was never prepared, served asavailable: false):<state>:count:<source>:<period>→ record counters per year or month (published/reserved); the totalpublished:count:<source>being absent means the indexing pass never ran for that sourcestats:<source>:cvss_band:<band>[:<year>],stats:<source>:cvss_version:<version>[:<year>]→ CVSS distribution countersstats:<source>:time_to_exploit→ hash, the last time to exploit snapshotstats:<source>:scorecard:meta,stats:<source>:scorecard:<window|all>:<assigner>(hashes),stats:<source>:scorecard:ranking:<bucket>,stats:<source>:scorecard:records:<bucket>(zsets) → the assigner scorecard, prepared byscorecardand every reindex (seevulnerabilitylookup/scorecard.py)index:<source>:kev[:<catalog>]→ set of known-exploited records; EUVD ingestion maintains its own,euvd --stats-scanrebuilds the othersstats:sources→ set of sources that have a prepared figure
Cache layer (Valkey)#
Valkey serves as a fast in-memory cache running on a Unix socket (cache/cache.sock).
It handles Pub/Sub messaging between feeders and the web layer, temporary data caching, and real-time
event distribution to services such as Meilisearch and the email notification system.
Backend (Feeders)#
The backend consists of 40+ feeders responsible for downloading security advisories from various sources.
All feeders inherit from the AbstractFeeder base class (CSAF-based feeders use CSAFGeneric).
Each feeder publishes collected data to Valkey Pub/Sub channels, enabling seamless integration with downstream services.
PostgreSQL database#
PostgreSQL stores user accounts, comments, bundles, sightings, watchlists, organizations, and KEV catalogs. The web application uses SQLAlchemy as its ORM with Alembic for schema migrations.
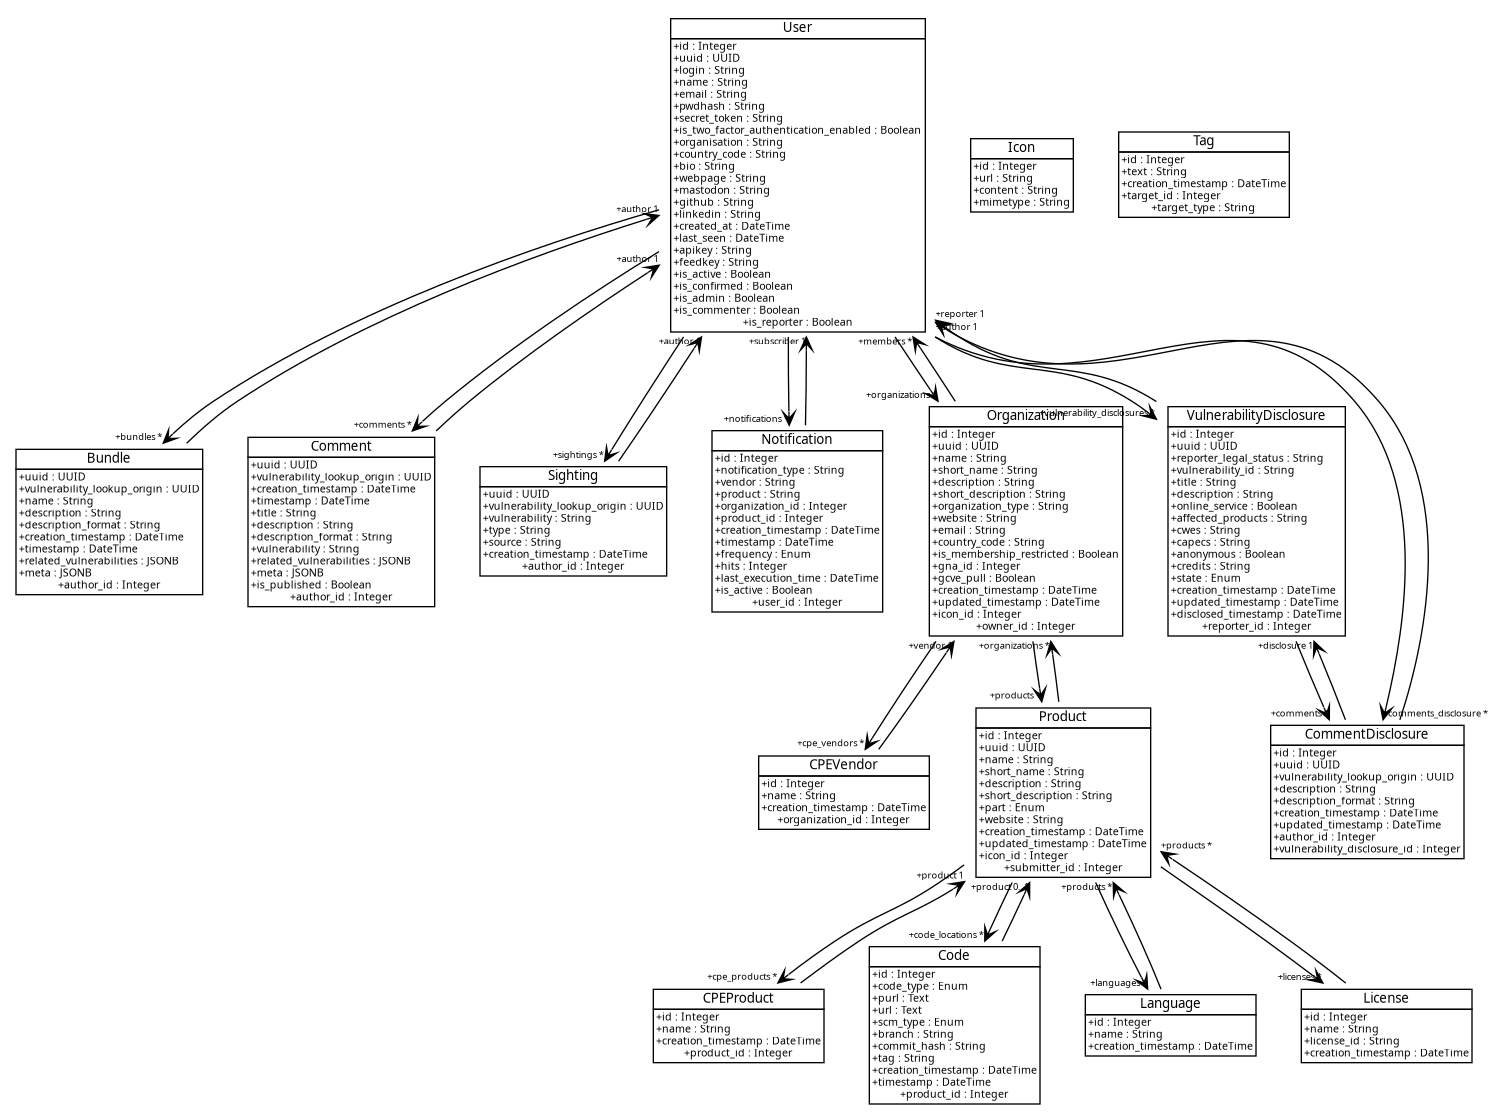
Fig. 2 Database models diagram#
Web layer (Flask)#
The web interface is a Flask application served by Gunicorn (default port 10001).
Views are organized as Blueprints and the REST API is available under /api/.
User authentication is handled by Flask-Login with optional two-factor authentication.
When user accounts are enabled (user_accounts: true in config/generic.json),
the platform supports comments, bundles, sightings, watchlists, and the CVD workflow.
Tools#
It is possible to extend Vulnerability-Lookup functionalities thanks to its API and various tools. For example:
PyVulnerabilityLookup — Python client library for the REST API.
FediVuln — publish vulnerability updates to the Fediverse via the Pub/Sub streaming service.
ML-Gateway — AI-powered severity classification, ATT&CK technique suggestions and bi-encoder similarity searches (VLAI).